Automation multiplies whatever its instructions contain
A command that saves ten minutes on one website can save hours across a managed fleet. The same command can reproduce an incorrect assumption across every site it touches. Scale does not distinguish good automation from bad automation; it amplifies both.
For that reason, Osiris treats fleet maintenance as a controlled deployment problem rather than a collection of unattended scripts. The purpose of automation is to make repeatable evidence and carefully bounded actions easier—not to remove accountability.
A safe system needs to know which sites are eligible, what may change, which preconditions must be true, how success will be measured, when execution must stop, and how the previous state can be restored. If any of those answers is missing, the task is not ready for fleet-wide execution.
A canary is a real environment with deliberately limited exposure
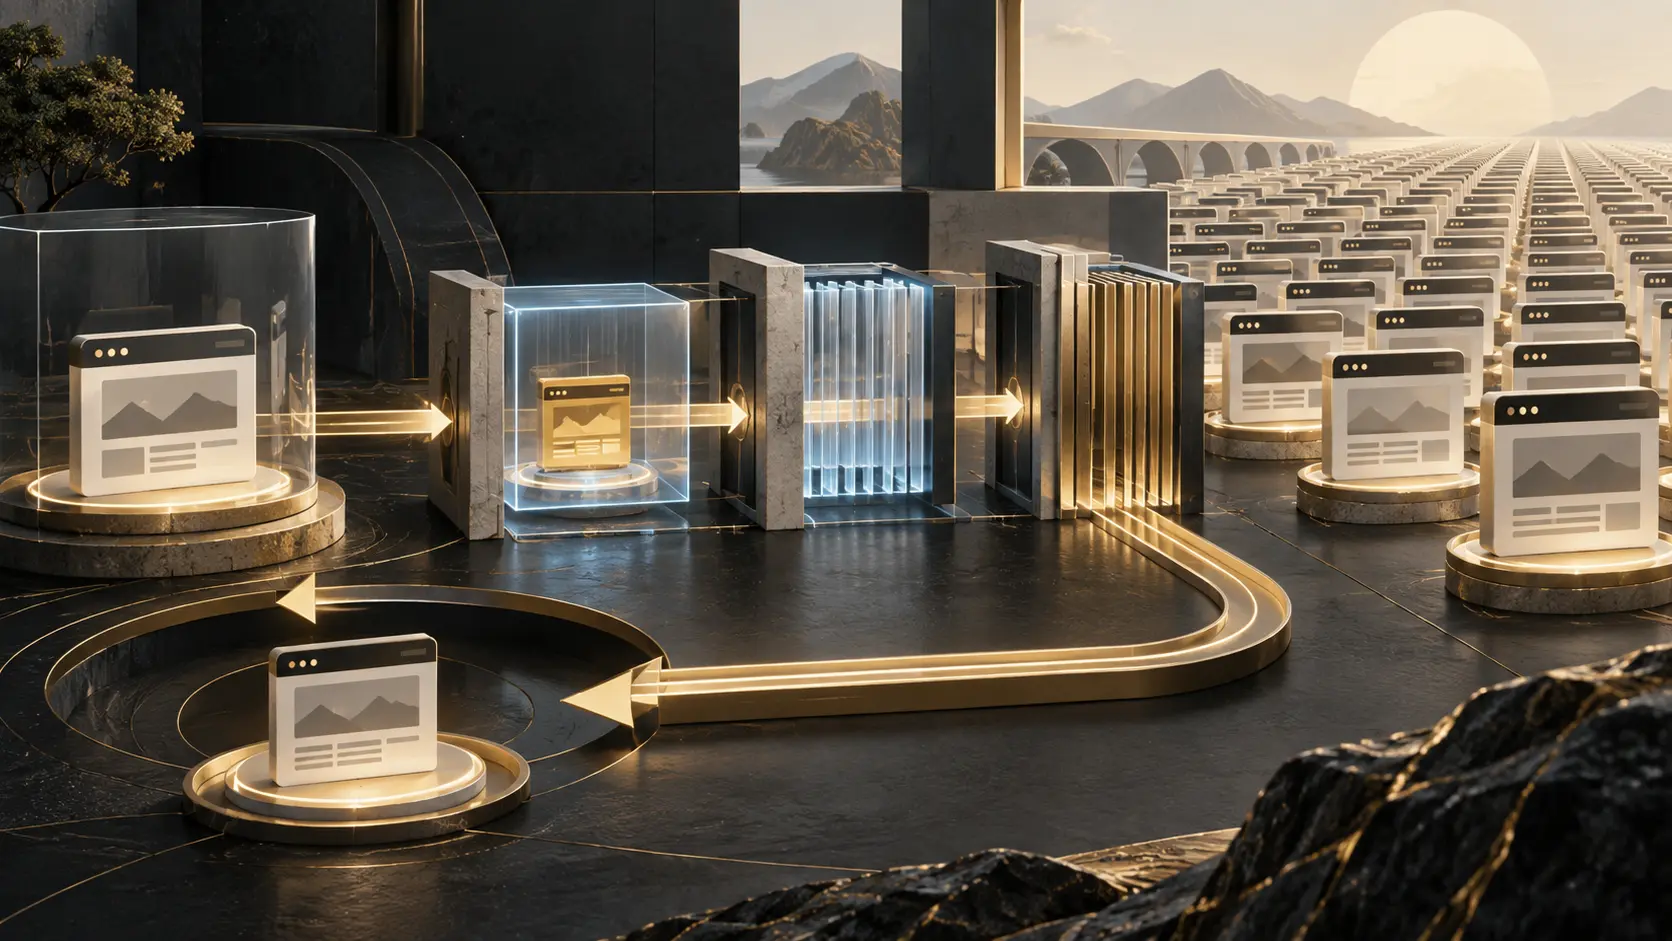
Canary testing applies a proposed change to one carefully selected environment before expanding it. The canary should be representative enough to expose meaningful incompatibilities while limiting the consequences of failure. It should not be the highest-value site, the most unusual application, or an environment without a dependable recovery path.
The canary run evaluates the complete workflow: authentication, privilege escalation, backups, maintenance mode, update behavior, cache clearing, application checks, log inspection, and rollback. Passing a syntax check is not sufficient. A change must be proven through visitor-facing and administrative journeys that matter to the site.
Only after evidence from the canary meets defined success criteria should the system consider a broader cohort.
Preflight checks protect the boundary before work begins
Many automation failures are not caused by the intended maintenance action. They result from an incorrect path, unexpected ownership, missing storage, a different server layout, an unavailable backup destination, a disabled service, or a permission model that does not match the script’s assumptions.
Preflight checks should verify identity, host, application root, WordPress status, disk space, database access, backup capacity, ownership, expected services, and the exact privilege mechanism required. Sensitive system locations must be explicitly excluded from broad recursive operations. Variables, globs, and discovered paths need validation before they are allowed to become mutation targets.
A failed preflight is a successful safety outcome. The system should stop without partially executing the main operation and present the evidence required for a human decision.
Privilege should be narrow, legible, and testable
Fleet tools sometimes need elevated access to restart services, inspect protected logs, or operate as a site owner. That authority should be expressed through narrowly scoped commands and explicit trust boundaries. A maintenance tool should not gain broad ownership of system security configuration merely because recursive file operations are convenient.
The complete privilege path matters: not just the policy file, but the ownership and permissions of each trusted directory leading to it. A single incorrect ownership transition can make the administrative mechanism unusable even when the intended policy text is correct.
Safe automation validates the trust path before and after any privileged installation. It treats operating-system security configuration as protected infrastructure, keeps application artifacts in dedicated directories, and refuses to normalize permissions outside its declared scope.
Rollback must exist before the forward action
A backup is not automatically a rollback plan. The system needs to know what was captured, where it is stored, whether it is readable, how restoration would occur, and which external changes—such as DNS, certificates, or package repositories—must also be reversed.
For WordPress updates, rollback may include the database, plugin or theme package, configuration files, cache state, and any generated assets. For server tooling, it may include service units, policy files, application releases, and configuration backups. Each artifact should be tied to the run that created it.
The safest remediation is often the smallest reversible change. If a verification gate fails, the tool should stop, preserve evidence, and restore only what the failed operation changed rather than launching a broad cleanup.
Independent health checks prevent self-certification
An automation process should not declare success merely because its final command exited zero. The website must be observed from outside the process that changed it. HTTP status, canonical redirects, representative pages, assets, login behavior, REST endpoints, forms where safe, PHP/server logs, database integrity, scheduled tasks, and performance indicators provide independent evidence.
Checks should distinguish visitor impact from harmless command-line warnings. They should also recognize transient maintenance behavior and retry carefully without hiding a persistent defect. If the automation cannot establish the expected outcome, it must report uncertainty instead of converting it into a green status.
Human review remains essential for ambiguous findings, unexpected infrastructure differences, and any decision that changes the approved scope.
The safest fleet system learns through reviewed evidence
A mature maintenance platform evolves after each verified run. Noisy checks are refined. Missing preconditions are added. Unsafe path assumptions become regression tests. Recovery instructions are validated. Exceptions are documented rather than silently normalized.
This learning loop is controlled by people. A model or script can help compare results, identify repeated patterns, and propose improvements, but it should not grant itself new privileges or expand its mutation scope. Changes to the automation are reviewed and tested through the same canary discipline as changes to a client site.
The goal is not unattended activity. It is dependable technical stewardship at a scale that would be impractical through manual repetition alone. Canaries, boundaries, rollback, independent verification, and accountable review make that scale useful rather than dangerous.